这个周末,苏生不惑又写了个新脚本


苏生不惑第
383篇原创文章,将本公众号设为星标,第一时间看最新文章。
之前分享过我写的工具 整理下苏生不惑开发过的那些软件和脚本 ,周末又完善了下批量下载知乎文章,回答,想法生成pdf电子书,这里以腾讯文档这个号为例,下载效果:
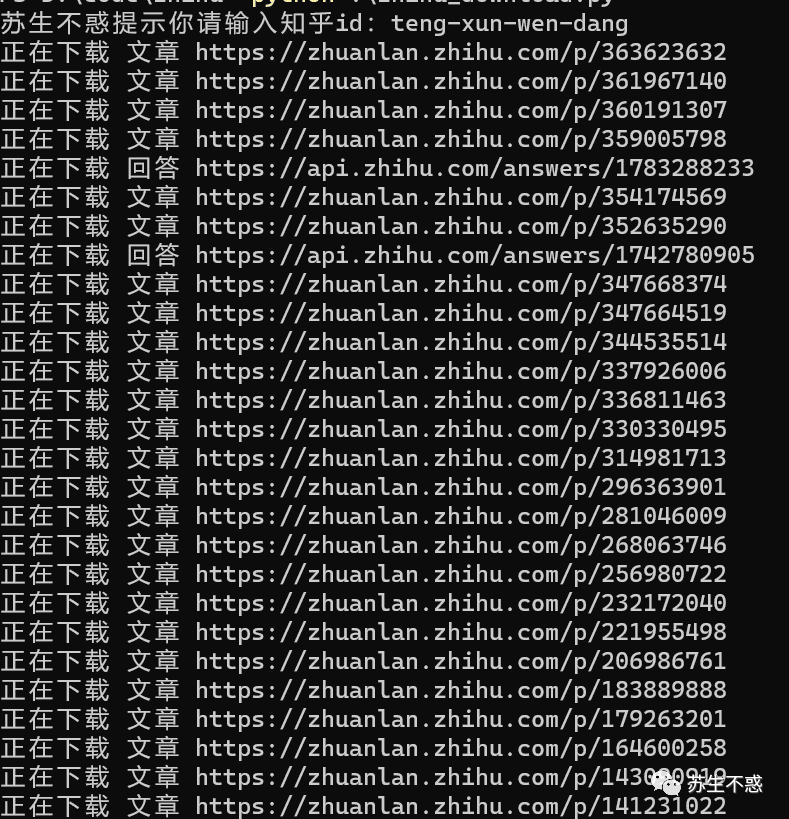
下载的文件在3个目录:文章,回答和想法。
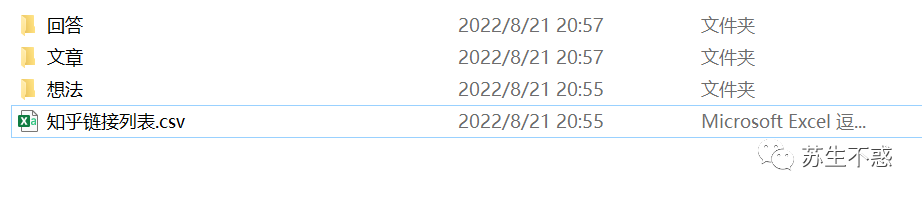
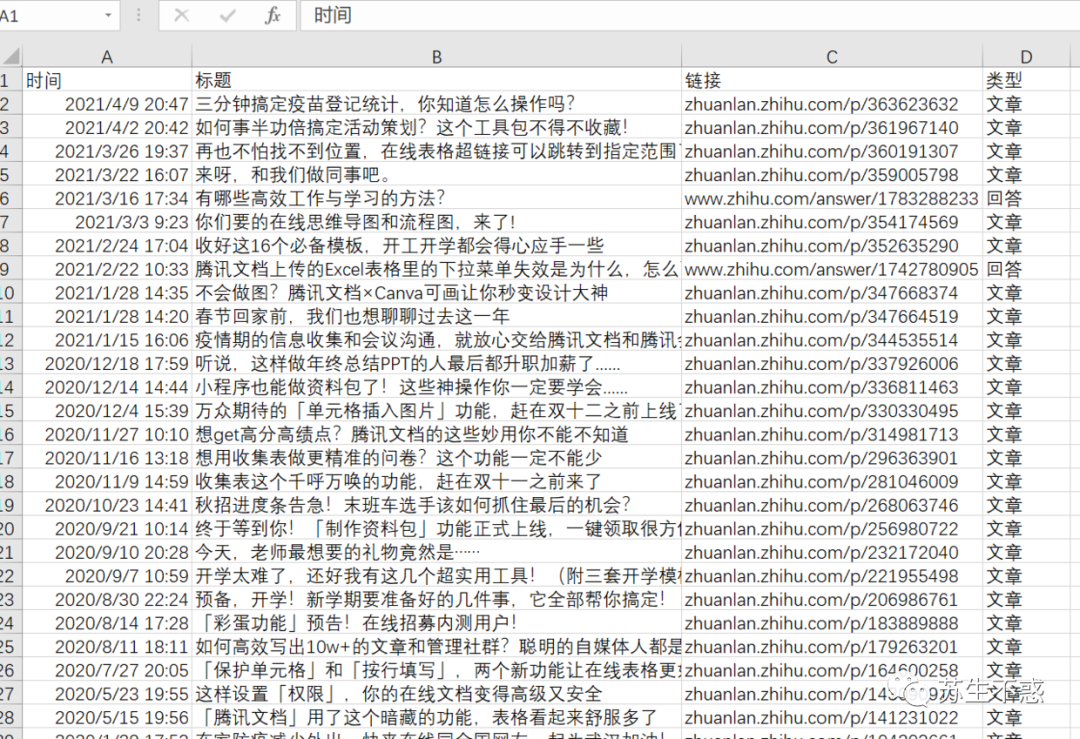
excel里是所有回答,文章和想法的链接列表,包括发布时间,标题和链接地址,及类型(文章,回答和想法)。
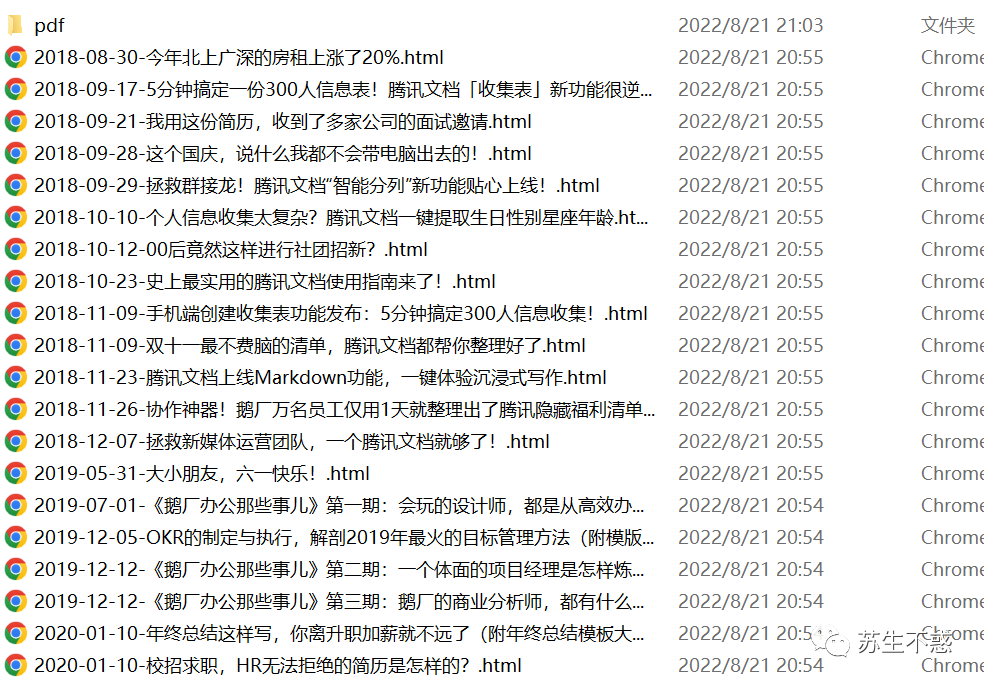
然后用脚本将下载的html批量转pdf:
def export_pdf():
    import pdfkit,os
    for root, dirs, files in os.walk('.'):
     for name in files:
      if name.endswith(".html"):
       print(name)
       try:
         pdfkit.from_file(name, 'pdf/'+name.replace('.html', '')+'.pdf')
       except Exception as e:
             print(e)
export_pdf()
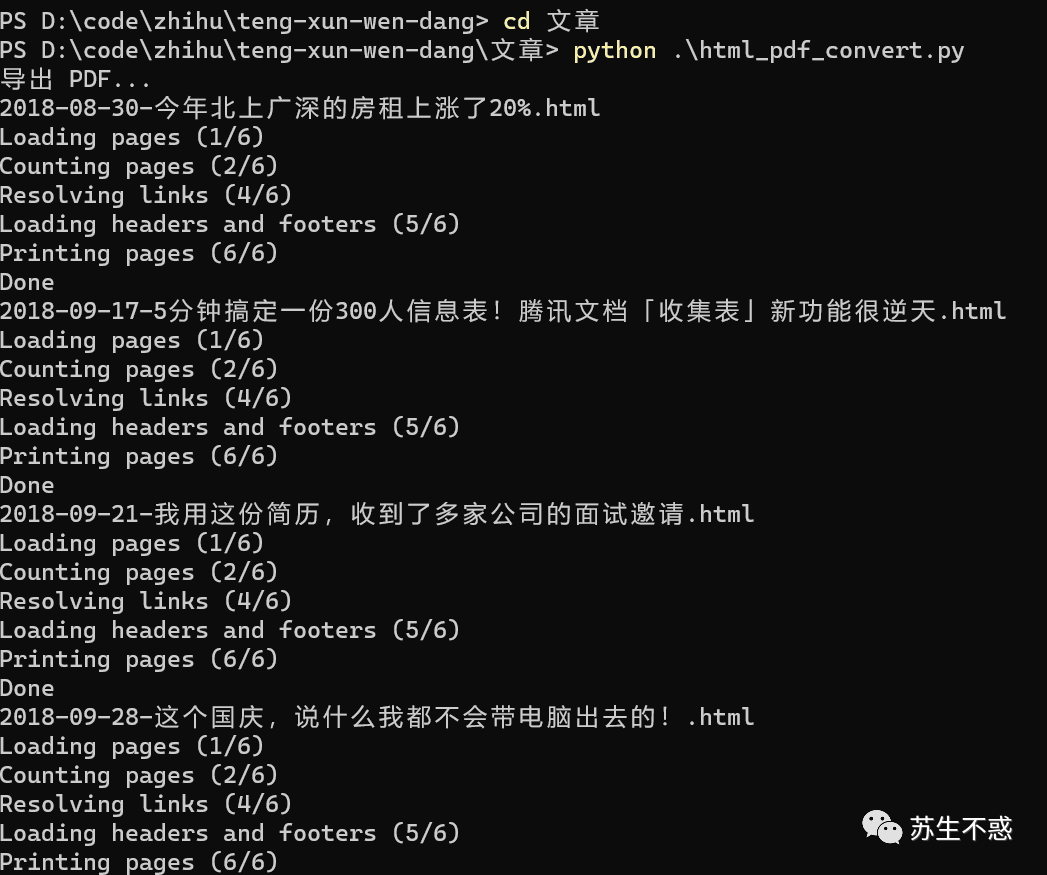
最后将所有pdf合成一个pdf文件,并生成书签目录苏生不惑又写了个小工具
from PyPDF2 import  PdfFileReader, PdfFileWriter,PdfFileMerger
file_writer = PdfFileWriter()
num = 0
for root, dirs, files in os.walk('.'):
    for name in files:
        if name.endswith(".pdf"):
            print(name)
            file_reader = PdfFileReader(name)
            file_writer.addBookmark(html.unescape(name).replace('.pdf',''), num, parent=None)
            for page in range(file_reader.getNumPages()):
                num += 1
                file_writer.addPage(file_reader.getPage(page))
with open(r"公众号苏生不惑历史文章合集.pdf",'wb') as f:
    file_writer.write(f)
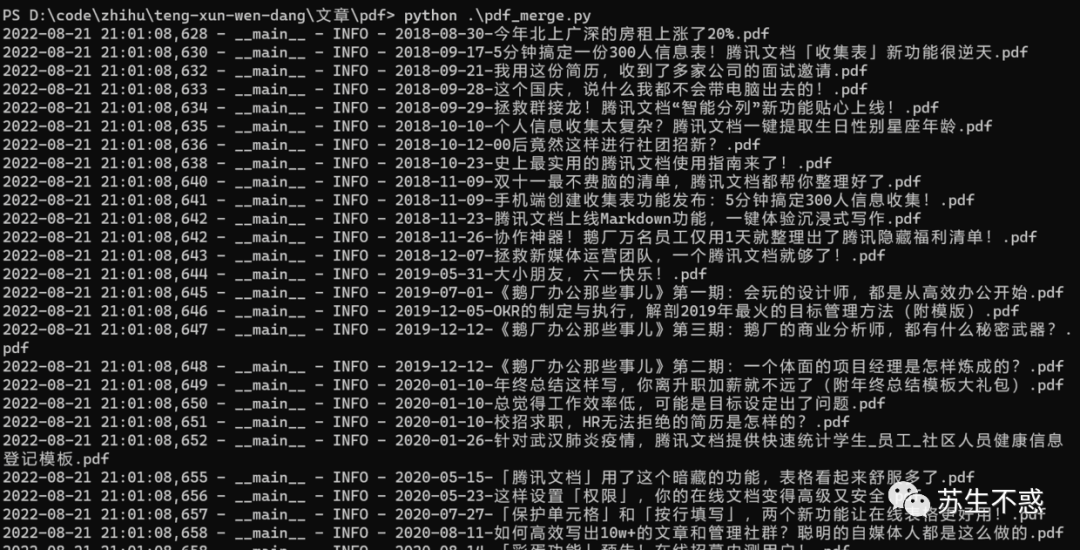
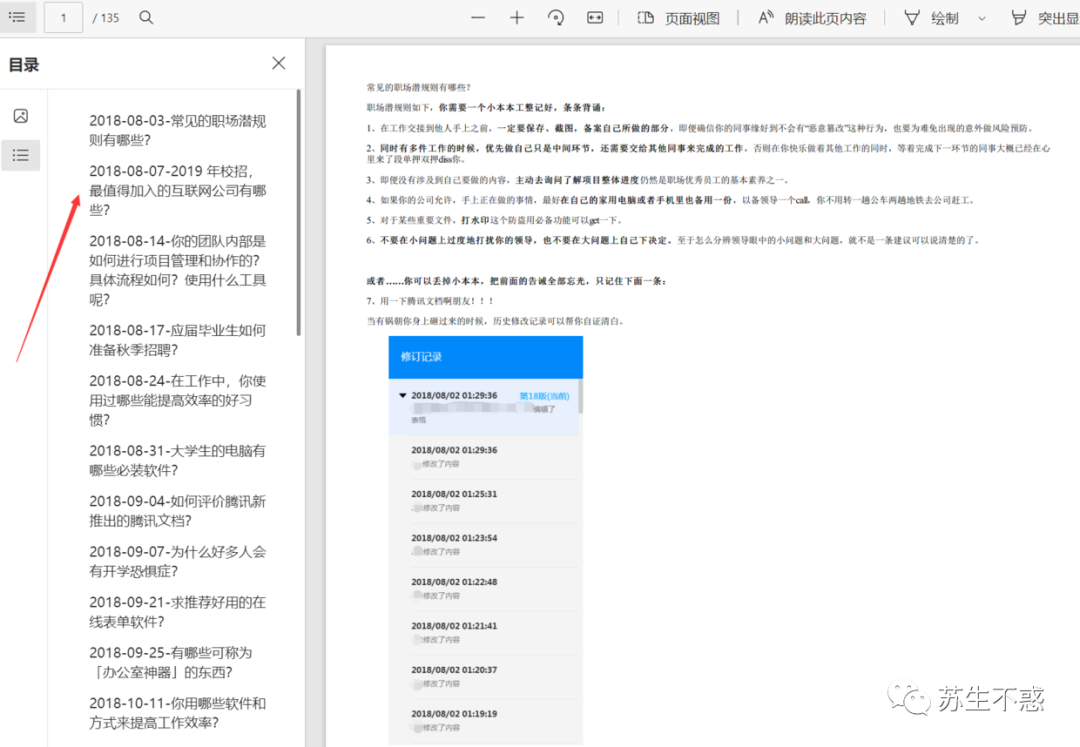
最后合成的一个pdf文件效果如图,点击左侧标题跳转到对应回答或者文章:
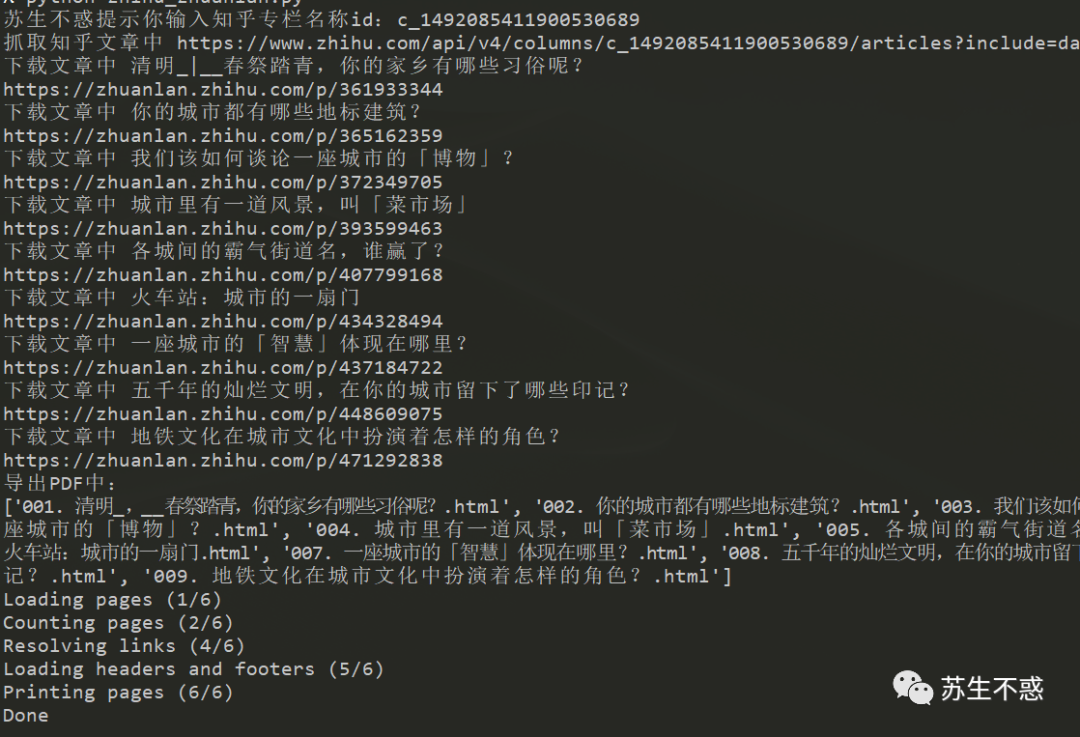
如果只是批量下载知乎专栏的文章用这个工具周末又写了个知乎专栏批量下载工具,顺便通知个事,输入知乎专栏id即可批量导出知乎专栏文章为pdf ,比如 https://www.zhihu.com/column/c_1492085411900530689 这个专栏,导出效果:
最后生成的专栏pdf文件:
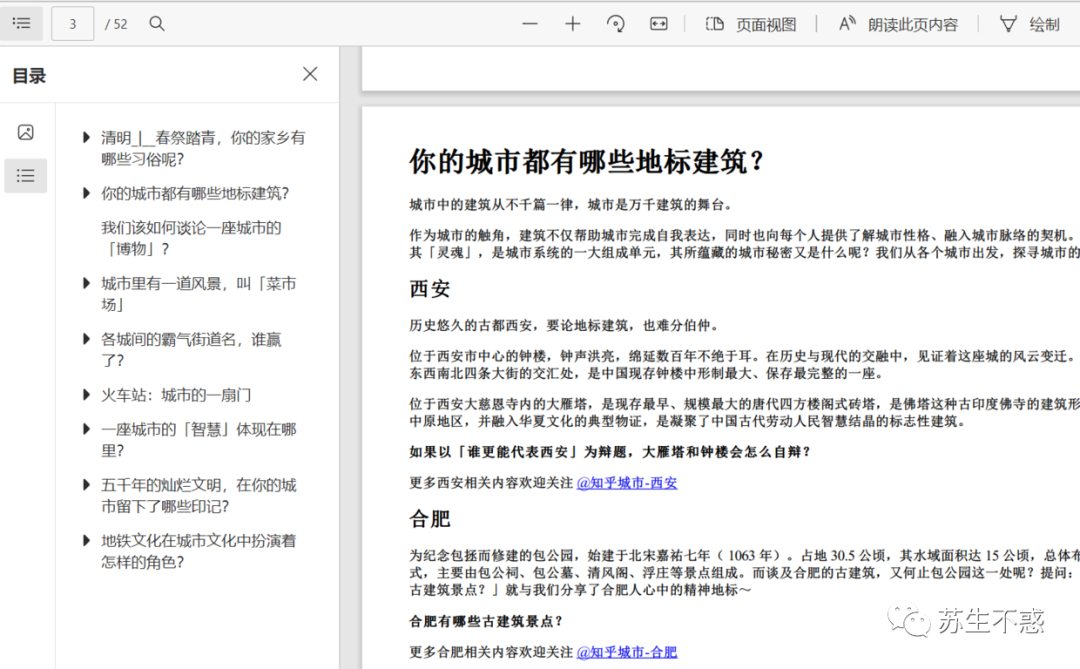
还有知乎问题下所有回答的抓取:
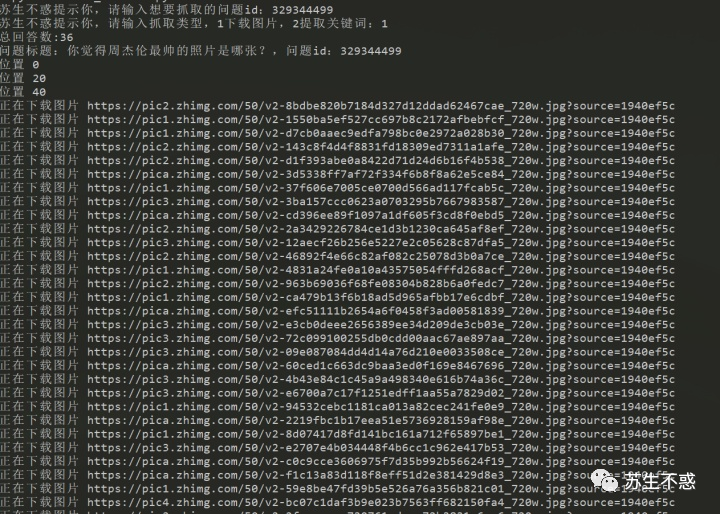
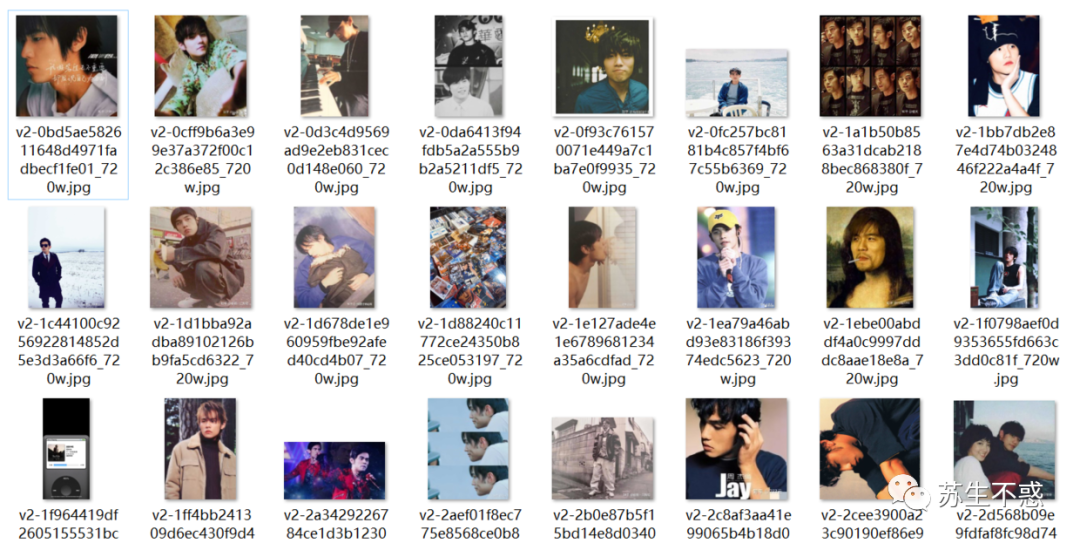
输入知乎问题id,很快就批量下载了上百个回答里周杰伦的图片:
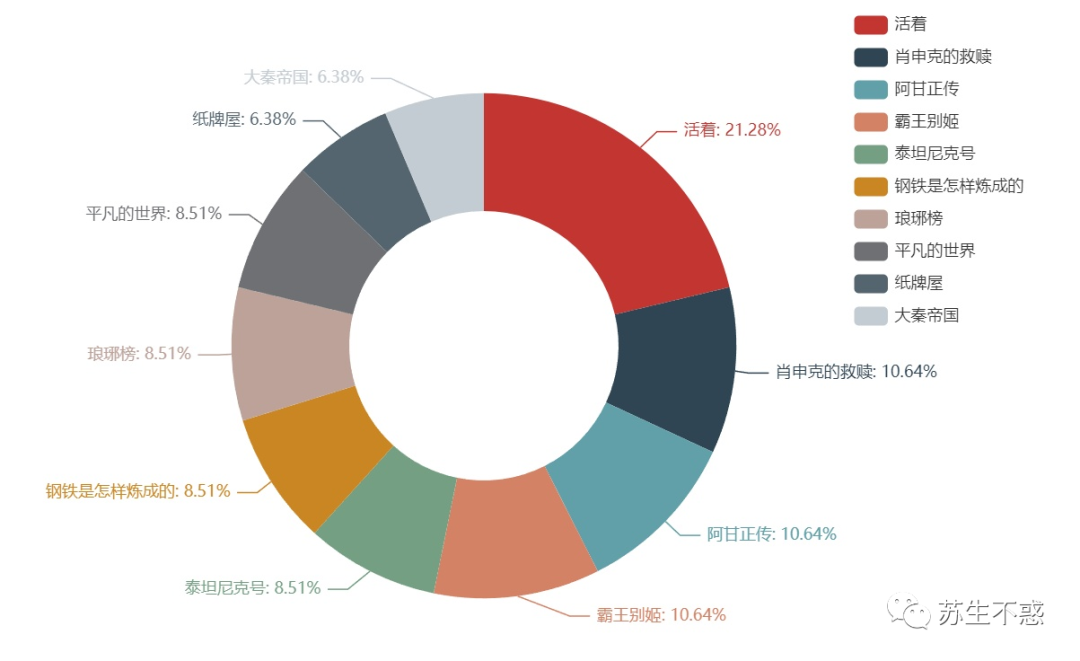
还可以分析所有回答里的关键词分布,代码:
df = pd.DataFrame(pandas_data, columns=['name', 'counts'])
       df.sort_values(by=['counts'], ascending=False, inplace=True)
       books = df['name'].head(10).tolist()
       counts = df['counts'].head(10).tolist()
       print(',  '.join(books))
       bar = (
           Bar()
               .add_xaxis(books)
               .add_yaxis("", counts)
       )
       pie = (
           Pie()
           .add("", [list(z) for z in zip(books, counts)],radius=["40%", "75%"], )
           .set_global_opts(title_opts=opts.TitleOpts(title="饼图",pos_left="center",pos_top="20"))
           .set_global_opts(legend_opts=opts.LegendOpts(type_="scroll", pos_left="80%", orient="vertical"))
           .set_series_opts(label_opts=opts.LabelOpts(formatter="{b}: {d}%"), )
       )
       pie.render(str(question_id) +'.html')
       df.to_csv(str(question_id) +".csv",encoding="utf_8_sig",index=False)
效果:
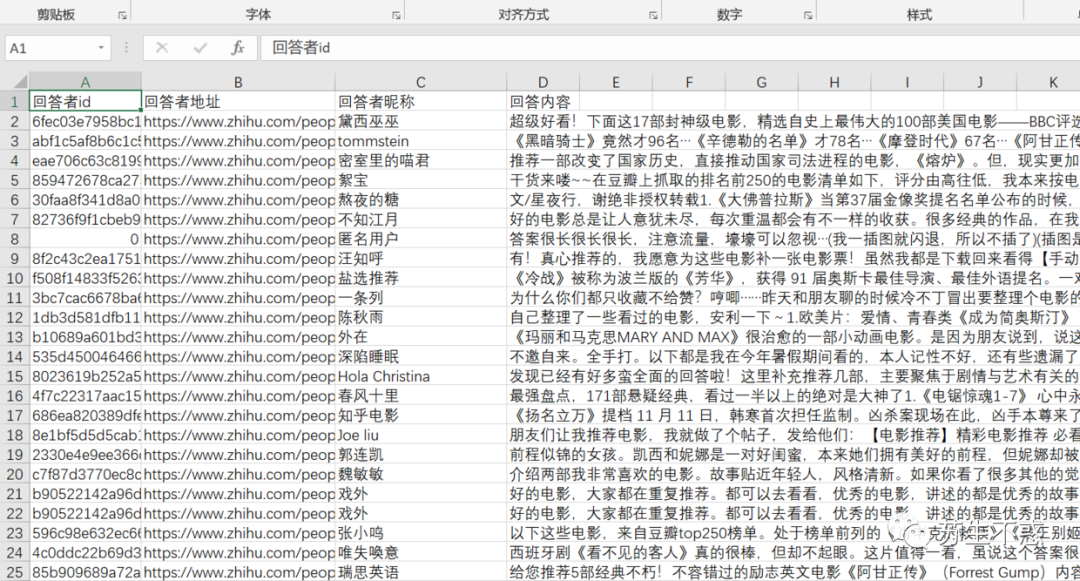
回答内容也批量下载到excel,包括每个回答人的昵称和回答内容:
说完知乎再说微博,之前分享过微博批量下载一键批量下微博内容/图片/视频,获取博主最受欢迎微博,图片查找微博博主 ,这次加上微博文章批量下载,导出的微博内容如图:
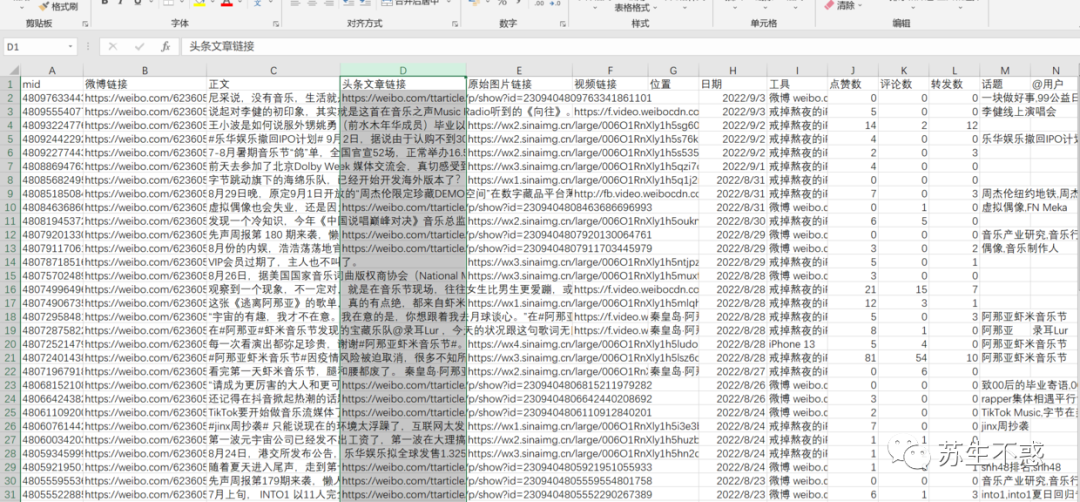
然后将excel里的头条文章链接下载为html,代码如下:
df = pandas.read_csv(f'{uid}.csv',encoding='utf_8_sig')
df = df[df['头条文章链接'].notnull()]
urls=df.头条文章链接.tolist()
for url in urls:
 try:
  res=requests.get(url,headers=headers, verify=False)
  title = re.search(r'<title>(.*?)</title>',res.text).group(1)
  weibo_time = re.search(r'<span class="time".*?>(.*?)</span>',res.text).group(1)
  if not weibo_time.startswith('20'):
   weibo_time=time.strftime('%Y')+'-'+weibo_time.strip().split(' ')[0]
  with open(weibo_time+'_'+trimName(title)+'.html', 'w+', encoding='utf-8') as f:
   f.write(res.text.replace('"//','https://'))
   print('下载微博文章',url)
 except Exception as e:
  print('错误信息',e,url)
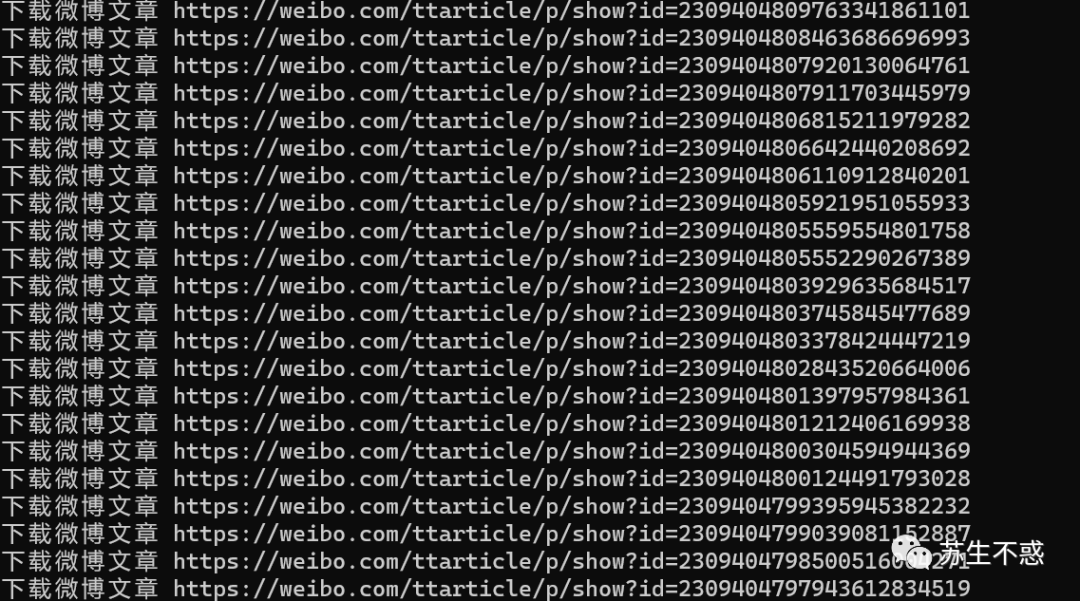
下载效果如图:
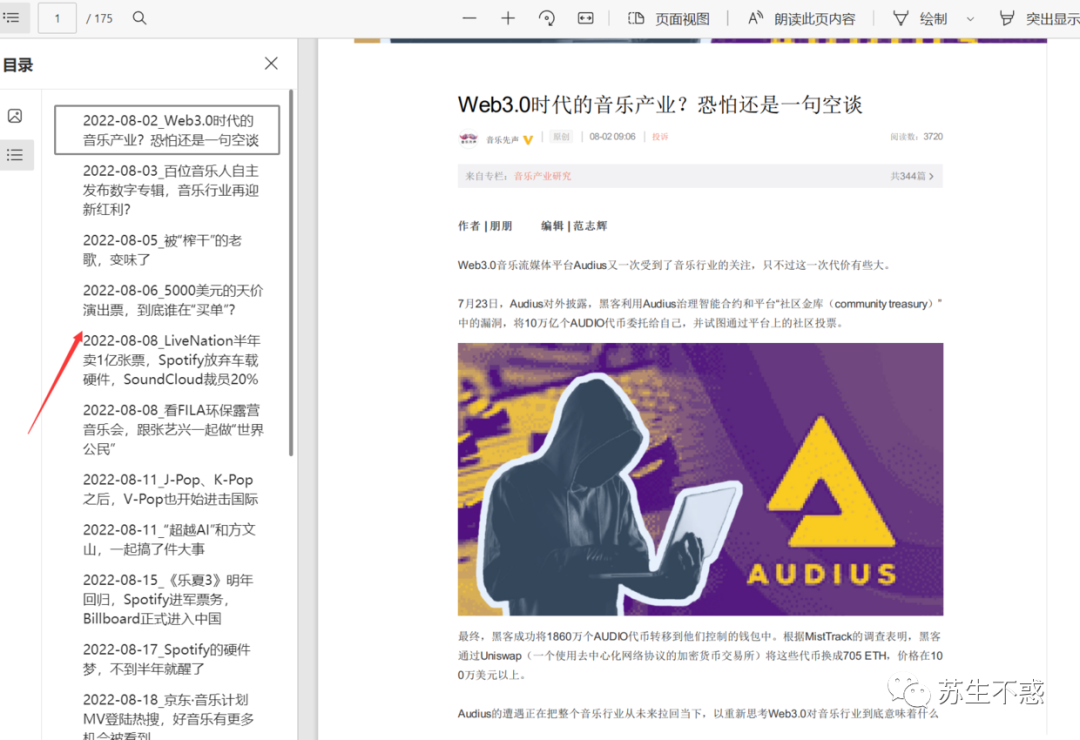
最后合成一个pdf文件,文章发布时间和标题作为书签。
本文参与 腾讯云自媒体同步曝光计划,分享自微信公众号。
原始发表:2022-09-07,如有侵权请联系 cloudcommunity@tencent.com 删除
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号